Chapter 8: Tools & Technology
Principles in play. Tools serve principles, never the reverse. This chapter mostly advances Automation and Efficiency and Knowledge Sharing (Chapter 2); a tool that serves neither is just a new thing to maintain.
Buy Capabilities, Not Product Names
Operations teams need a small set of capabilities:
| Capability | What it must enable | Practices served |
|---|---|---|
| Observability | Detect user-visible failure, investigate it, and measure service levels | Service Level; Incident and Problem; Capacity and Performance |
| Incident response | Route alerts, coordinate responders, communicate status, and preserve a timeline | Incident and Problem |
| Automation | Provision infrastructure, enforce configuration, and execute repeatable runbooks | Change and Configuration; Release; Service Request |
| Knowledge | Store searchable runbooks, decisions, ownership, and recovery procedures | Knowledge and Documentation; Team and Skill Development |
| Delivery control | Review, validate, deploy, and roll back changes | Change and Configuration; Release |
| Asset and cost visibility | Connect services to owners, infrastructure, vendors, and spending | Asset; Vendor and Contract; Financial |
| Policy enforcement | Test required controls before a change reaches production | Change and Configuration; Risk and Compliance |
Product names are examples, not architecture. Vendors change pricing, merge products, and retire features. Review named recommendations before buying; keep the capability requirements stable.
Rule: Do not buy a tool to create a process you do not yet understand. It will automate confusion.
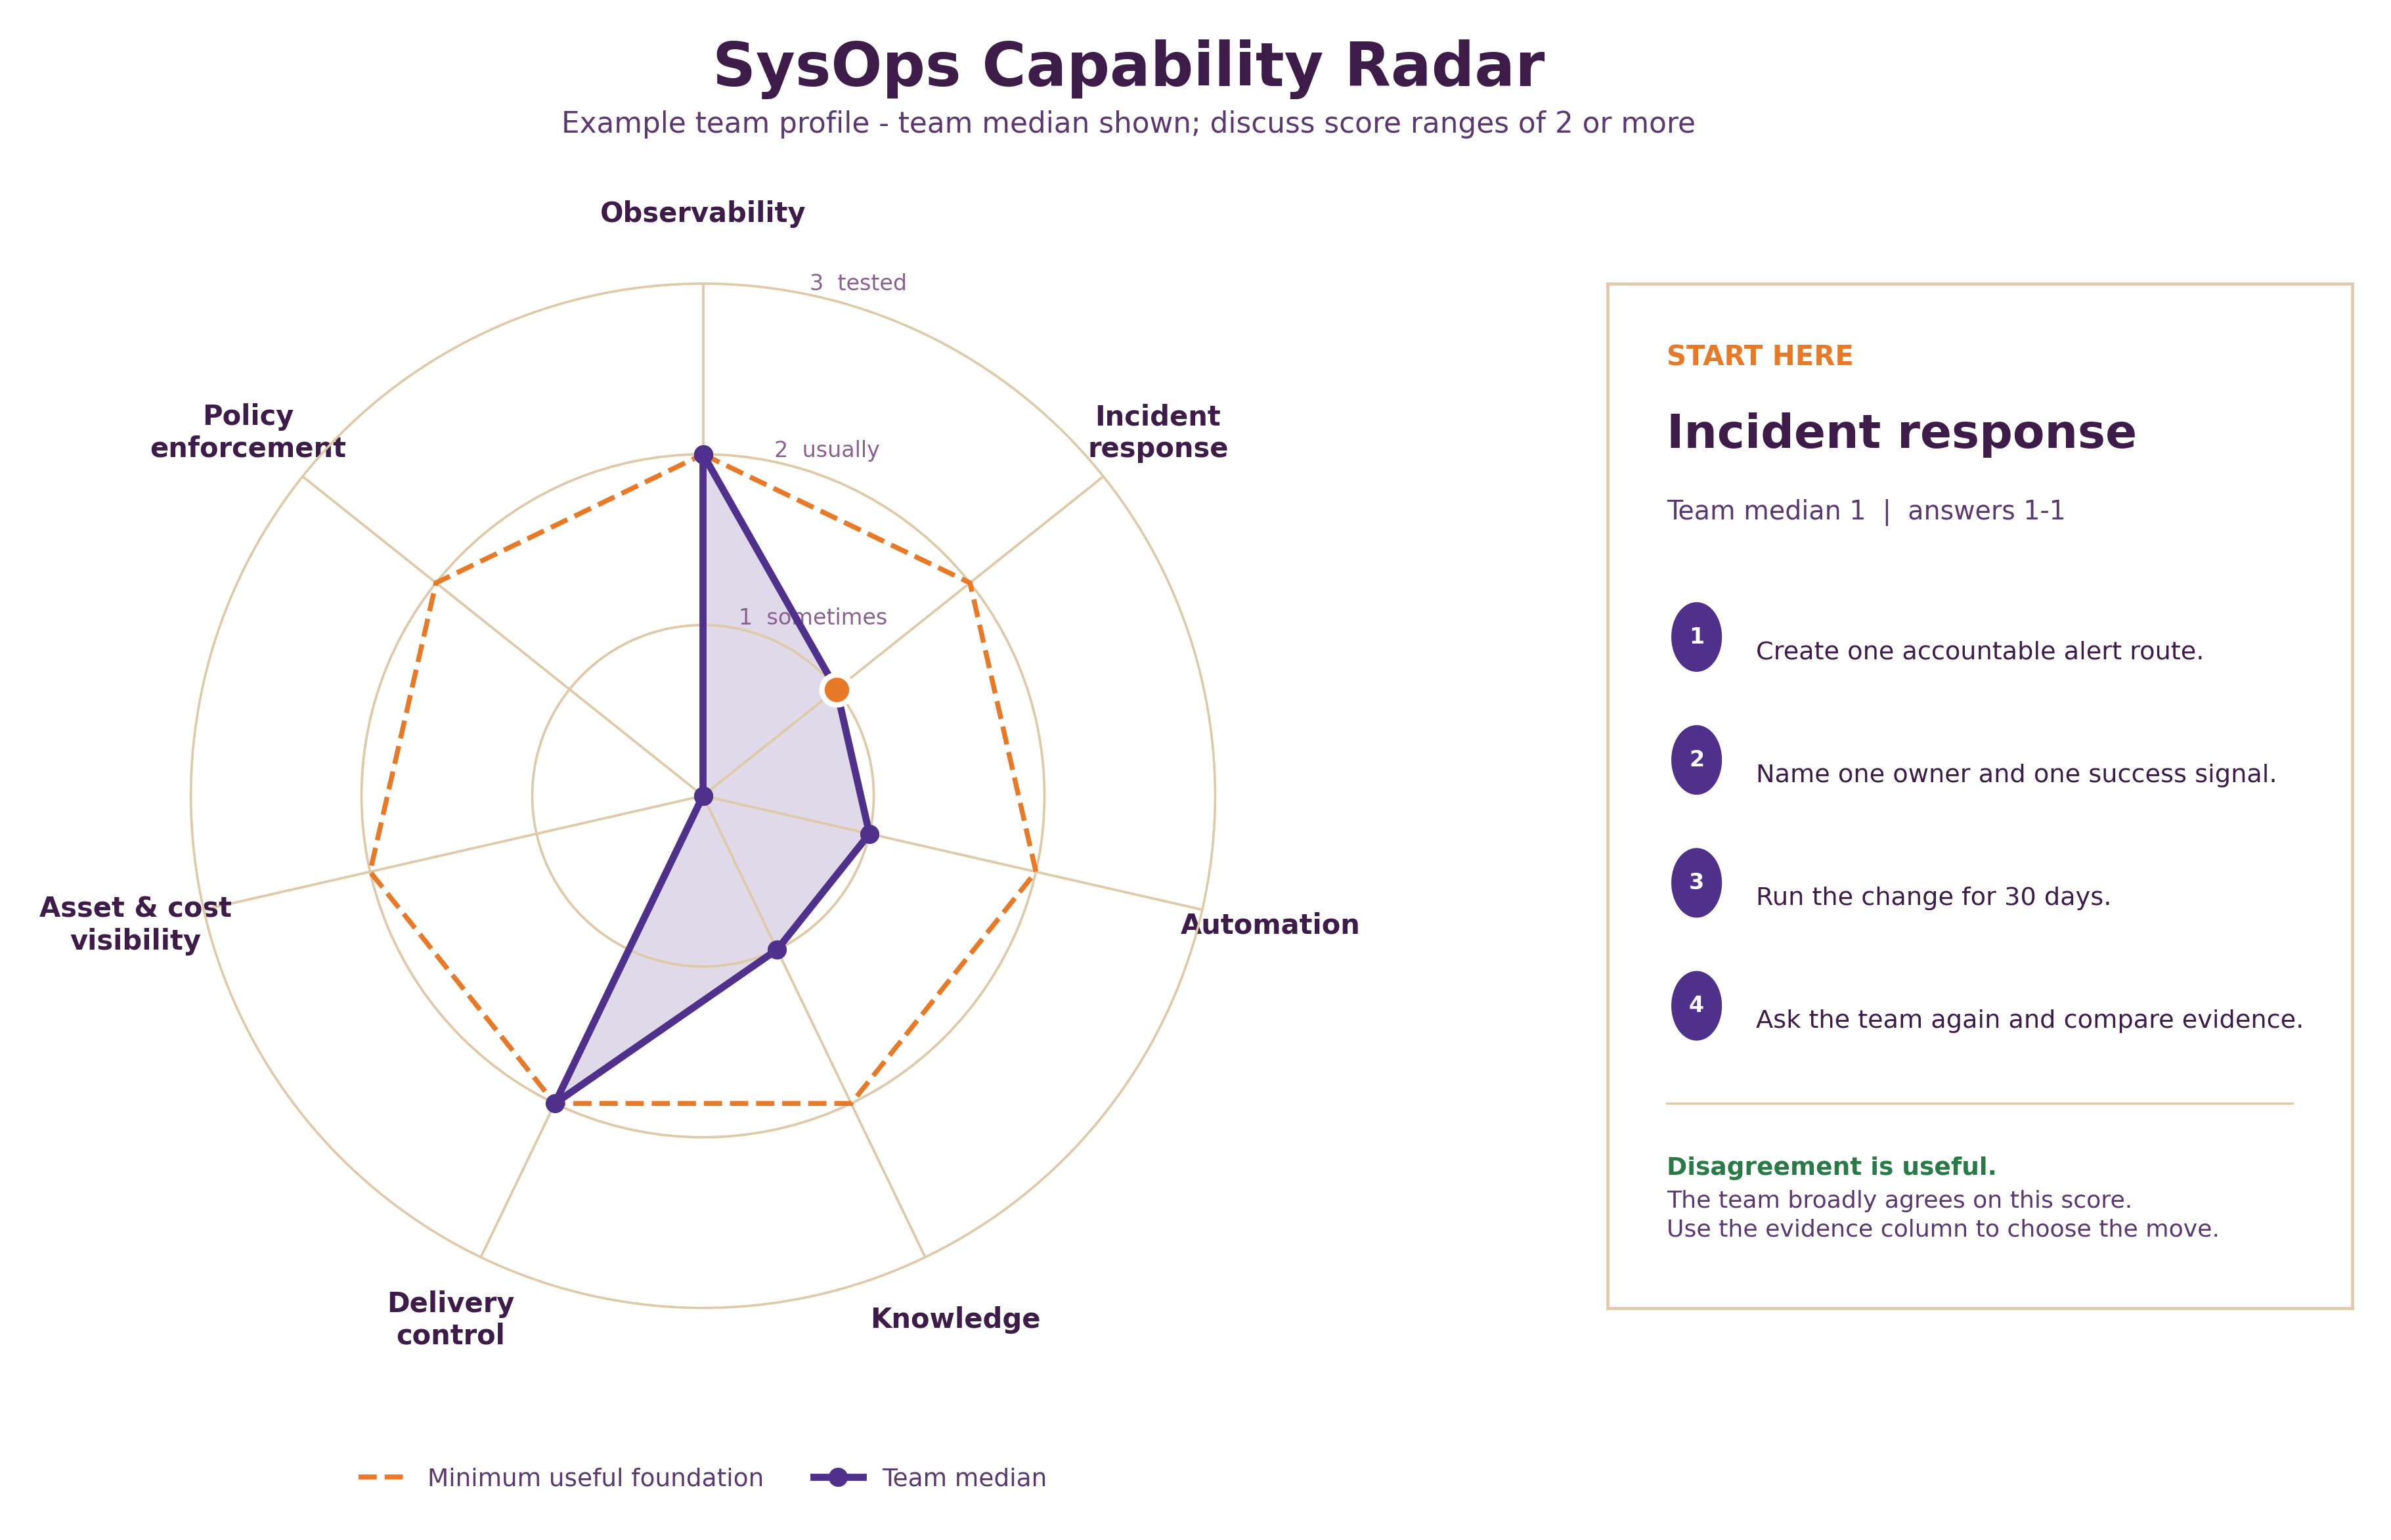
Capability Radar: Find Your First Gap
Use the radar to decide where to begin, not to produce a maturity score for management.
Diagram: An example team has basic observability and delivery control, but incident response and knowledge are still ad hoc. Those foundational gaps come before advanced policy or platform tooling.
Team Questionnaire
Give everyone 10 quiet minutes to score the questions before discussing them. Use the same simple scale for every row:
| Score | Plain meaning |
|---|---|
| 0 | No |
| 1 | Sometimes, or only one person knows how |
| 2 | Usually; the steps are written and others can do it |
| 3 | Yes; we test it and fix it when it stops working |
Copy and fill in this table:
| Capability | Ask the team | Score | What proves our answer? | One small next move |
|---|---|---|---|---|
| Observability | Do we know something is broken before users tell us? | __ | ||
| Incident response | When an alarm goes off, does everyone know who answers and what to do? | __ | ||
| Automation | Does the computer handle boring repeated work, or do people repeat the steps? | __ | ||
| Knowledge | Could a teammate who is not the usual expert follow written steps safely? | __ | ||
| Delivery control | Can we make a change, check it worked, and undo it if it did not? | __ | ||
| Asset and cost | Do we know what we run, who owns each thing, and roughly what it costs? | __ | ||
| Policy | Are important safety and security rules checked before a change goes live? | __ |
Draw the Team Radar
- Ask each person to answer alone. This prevents the loudest voice from setting the team’s score.
- Copy
templates/capability-radar.csvand add one row per person using the same 0–3 scores. - Generate the radar:
| |
The plotted point is the median team answer for each capability. The diagram also reports the lowest and highest answer for the recommended starting capability. If the spread is 2 or more, discuss why people experience the same process differently before choosing a tool.
Choose the First Move
- Compare answers. A large disagreement means the process is unclear; do not average it away.
- Require one example in “What proves our answer?” A tool license is not proof.
- If observability, incident response, or knowledge scores below 2, start with the lowest of those foundations.
- Otherwise, choose the low-scoring row connected to the most painful recurring problem.
- Write one small move, one owner, and a date. Repeat the questionnaire after 30 days and check whether the real pain changed.
The radar is a team conversation, not a report card for management.
The Minimum Viable Stack
Start with tools the organization already operates and trusts. A small team normally needs only:
- Monitoring and alerting with one reliable on-call route.
- A ticket or incident record with ownership and timestamps.
- Version control plus CI/CD for reviewed changes.
- One searchable home for runbooks and service ownership.
- A general automation tool for recurring work.
- A spreadsheet or simple table for services, assets, and costs.
Common starting choices include Prometheus and Grafana or a managed observability service; the existing ticketing and chat systems; GitHub or GitLab CI; a repository or wiki for documentation; Ansible for configuration; and Terraform, OpenTofu, or a cloud-native provisioning service for infrastructure.
Do not add a CMDB platform, service catalog, internal developer platform, service mesh, dedicated FinOps suite, or AIOps product until the scale or control requirement is visible and measurable.
Add Tools When the Constraint Appears
| Observed constraint | Smallest next step |
|---|---|
| Telemetry is tied to one backend | Standardize collection with OpenTelemetry |
| Deployments drift from reviewed configuration | Reconcile from Git with a GitOps controller |
| Teams repeatedly request the same service setup | Publish a reviewed template before considering a platform |
| Policy reviews are repetitive and inconsistent | Add policy checks to CI before buying a policy platform |
| Asset ownership no longer fits in a maintained table | Adopt a service catalog or CMDB with a named owner |
| Cloud spending cannot be attributed | Enforce tags and use provider cost reports before adding another product |
| Alert volume overwhelms responders | Delete or repair unactionable alerts before adding correlation software |
Selection Criteria
Evaluate tools against the work they remove, not the features they advertise.
| Criterion | Question |
|---|---|
| Need | Which current failure, delay, or manual task does this solve? |
| Fit | Does it support the team’s existing workflow and skills? |
| Reliability | What happens when this tool is unavailable during an incident? |
| Integration | Can data enter and leave through documented APIs or standard formats? |
| Security | Does access control, audit history, retention, and data location meet requirements? |
| Operations | Who upgrades, backs up, monitors, and supports it? |
| Cost | What is the full cost of licenses, hosting, integration, training, and migration? |
| Exit | How will the team export its data and replace the tool? |
Shortlist at most three candidates. Test them with one real workflow and real operators. A proof of concept succeeds only if it removes measurable work or risk; a polished demo is not evidence.
Integration Rules
Prefer a few boring connections:
- Use single sign-on and role-based access.
- Keep service names and ownership identifiers consistent across systems.
- Send alerts to one accountable route.
- Link every alert to a runbook or an explicit diagnostic action.
- Link changes to deployments and incidents so failures can be correlated.
- Preserve audit history for production actions.
- Use APIs and open telemetry formats where practical.
Avoid building a central integration platform merely to connect tools. Direct integrations are easier to understand until their maintenance cost becomes a demonstrated problem.
Modern Platform Patterns
These patterns are useful at the right scale, but none is a prerequisite for SysOps:
| Pattern | Use it when | Skip it when |
|---|---|---|
| GitOps | Declarative environments drift and reviewed reconciliation is valuable | Scripts or CI already deploy a small estate reliably |
| Internal developer platform | Several teams repeat the same provisioning and delivery work | One team can maintain a few templates |
| Policy as code | The same objective control must be checked on every change | Reviews are rare or depend mainly on human judgment |
| Service mesh | Service-to-service identity and traffic policy cannot be handled at the platform edge | The operational burden exceeds the traffic problem |
| ChatOps | Shared commands reduce incident context switching and retain a useful log | Chat becomes an unreviewed production shell |
Any production action triggered from chat or self-service must retain the same authorization, approval, audit, and rollback controls as the underlying system.
Adoption Order
- Make monitoring and incident routing trustworthy.
- Put runbooks and ownership where responders can find them.
- Automate the repetitive work causing the most toil or risk.
- Connect changes, deployments, incidents, and service metrics.
- Add self-service or policy enforcement only after repeated demand appears.
Tool maturity is not the number of products installed. It is the amount of reliable work the team can perform without heroics.
← Previous: Chapter 7 - Metrics & Measurement | Next: Chapter 9 - Culture & Organization →